<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://blog.tangrs.id.au/feed.xml" rel="self" type="application/atom+xml" /><link href="https://blog.tangrs.id.au/" rel="alternate" type="text/html" /><updated>2026-09-16T08:17:16+00:00</updated><id>https://blog.tangrs.id.au/feed.xml</id><title type="html">tangrs</title><entry><title type="html">Exploring embedded root filesystems with QEMU and unshare</title><link href="https://blog.tangrs.id.au/2026/09/16/exploring-embedded-root-filesystems-using-qemu-and-unshare/" rel="alternate" type="text/html" title="Exploring embedded root filesystems with QEMU and unshare" /><published>2026-09-16T00:00:00+00:00</published><updated>2026-09-16T00:00:00+00:00</updated><id>https://blog.tangrs.id.au/2026/09/16/exploring-embedded-root-filesystems-using-qemu-and-unshare</id><content type="html" xml:base="https://blog.tangrs.id.au/2026/09/16/exploring-embedded-root-filesystems-using-qemu-and-unshare/"><![CDATA[<p>When reverse-engineering Linux-based embedded firmwares, it’s often useful to be able to run the firmware userspace (or other binaries like <code class="language-plaintext highlighter-rouge">/bin/sh</code>) in an emulated environment locally.</p>

<p>It’s very common to do so using a combination of QEMU user-space emulation, and <code class="language-plaintext highlighter-rouge">chroot</code>. For example:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>sudo apt install qemu-user
sudo chroot /path/to/embedded/rootfs /bin/sh
</code></pre></div></div>

<p>On the Ubuntu version I run, this works because the <code class="language-plaintext highlighter-rouge">qemu-user</code> package also installs a systemd service that adds <code class="language-plaintext highlighter-rouge">binfmt</code> interpreters that invokes the qemu binaries to emulate execution of non-native binaries. The <code class="language-plaintext highlighter-rouge">qemu-user</code> binaries are statically compiled, allowing them to be used even within a <code class="language-plaintext highlighter-rouge">chroot</code>.</p>

<p>However, using <code class="language-plaintext highlighter-rouge">chroot</code> is somewhat sub-optimal because the processes in this environment run as real root on the host. Vendor binaries may end up trashing the state of the host (block devices, network interface states, etc…) as part of how they operate. They may also make other assumptions like <code class="language-plaintext highlighter-rouge">init</code> being PID 1.</p>

<p>I’ve found that a much nicer way is to use <code class="language-plaintext highlighter-rouge">unshare</code> to create an unprivileged container instead of using <code class="language-plaintext highlighter-rouge">chroot</code>:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>unshare --fork \
    --user \
    --mount \
    --pid \
    --ipc \
    --uts \
    --time \
    --net \
    --map-root-user \
    --mount-proc \
    --root=/path/to/embedded/rootfs \
    /bin/sh
</code></pre></div></div>

<p>On Ubuntu, some hardening options may need to be relaxed to allow unprivileged users to create new user namespaces:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>sudo sysctl -w kernel.unprivileged_userns_clone=1
sudo sysctl -w kernel.apparmor_restrict_unprivileged_userns=0
</code></pre></div></div>

<p>This gives an environment where:</p>

<ul>
  <li>The program run is given PID 1</li>
  <li>The program run appears to be running as root (but in actuality, is limited in privileges as the user running <code class="language-plaintext highlighter-rouge">unshare</code>)</li>
  <li>Host processes aren’t visible</li>
  <li>Host network interfaces aren’t accessible (if networking is needed, it’s always possible to pipe through a <code class="language-plaintext highlighter-rouge">veth</code> interface)</li>
  <li>Changes to the hostname/time don’t affect the host</li>
  <li>Calling <code class="language-plaintext highlighter-rouge">reboot</code> or <code class="language-plaintext highlighter-rouge">poweroff</code> merely shuts down the container, rather than the host.</li>
</ul>

<p>This is much safer than giving full host root access, and is much closer to emulating a real execution environment for the firmware.</p>]]></content><author><name></name></author><summary type="html"><![CDATA[When reverse-engineering Linux-based embedded firmwares, it’s often useful to be able to run the firmware userspace (or other binaries like /bin/sh) in an emulated environment locally.]]></summary></entry><entry><title type="html">Getting root on on TP-Link Smart Switches using CVE-2026-1668 - Part 3</title><link href="https://blog.tangrs.id.au/2026/04/06/exploiting-cve-2026-1668-part-3/" rel="alternate" type="text/html" title="Getting root on on TP-Link Smart Switches using CVE-2026-1668 - Part 3" /><published>2026-04-06T00:00:00+00:00</published><updated>2026-04-06T00:00:00+00:00</updated><id>https://blog.tangrs.id.au/2026/04/06/exploiting-cve-2026-1668-part-3</id><content type="html" xml:base="https://blog.tangrs.id.au/2026/04/06/exploiting-cve-2026-1668-part-3/"><![CDATA[<p>In the <a href="/2026/03/24/exploiting-cve-2026-1668-part-2/">previous post</a>, I described how we can exploit CVE-2026-1668 to gain arbitrary code execution. In this post, I go into the details of building a useful exploit payload.</p>

<p>The final proof-of-concept exploit code is available at <a href="https://github.com/tangrs/cve-2026-1668-poc">https://github.com/tangrs/cve-2026-1668-poc</a>.</p>

<h2 id="popping-a-shell">Popping a shell</h2>

<p>The most common exploit payload is one that somehow gives the attacker interactive shell access to the vulnerable system (commonly known as <a href="https://en.wikipedia.org/wiki/Shellcode">shellcode</a>). When exploiting remote systems, the most basic form of such a payload on Linux looks something like:</p>

<ol>
  <li>Somehow obtain a TCP socket that is connected to the attacker’s machine.</li>
  <li>Redirect stdin, stdout and stderr (file descriptors 0, 1 and 2) to the socket using <code class="language-plaintext highlighter-rouge">dup2</code>.</li>
  <li>Exec a shell binary in interactive mode (i.e. <code class="language-plaintext highlighter-rouge">/bin/sh -i</code>).</li>
</ol>

<p>There are two approaches for obtaining a socket to the attacker’s machine:</p>

<ul>
  <li>Listen for a TCP connection on an unused port, and wait for the attacker to connect to it.</li>
  <li>Make a TCP connection to an attacker controlled IP address (i.e. a reverse-shell).
    <ul>
      <li>This is useful in cases where there are firewalls preventing inbound connections to the vulnerable system, but allows outgoing ones.</li>
    </ul>
  </li>
</ul>

<p>The attacker can use netcat to either connect to or accept a TCP connection from the remote end and interact with the remote shell.</p>

<p>For the proof-of-concept, I chose to implement the former approach.</p>

<h2 id="payload-crafting">Payload crafting</h2>

<p>The proof-of-concept payload has the following logical components:</p>

<ul>
  <li>The data that we need to overwrite the connection state-tracking data in memory to trigger the exploit.</li>
  <li>The actual MIPS instructions (i.e. the shellcode) that will be executed upon triggering the exploit.</li>
  <li>Any static data that the shellcode needs.</li>
</ul>

<p>While it’s possible to craft the payload entirely in a hex editor, doing so is incredibly time-consuming and error-prone. We can do much better by making good use of the GCC toolchain.</p>

<h3 id="using-the-assembler-to-encode-data">Using the assembler to encode data</h3>

<p>The initial part of the payload are various bits of data that overwrite the necessary structures in memory. While we could hand-craft this in a hex editor, it’s much neater and maintainable to encode this in assembler for many reasons:</p>

<ul>
  <li>We can have code comments that explain what each piece of data is doing.</li>
  <li>We can use assembler macros to generate data (e.g. generate padding with <code class="language-plaintext highlighter-rouge">.fill</code>).</li>
  <li>We can use linker symbols and expressions to avoid needing to calculate memory addresses by hand (e.g. <code class="language-plaintext highlighter-rouge">.word start</code> instead of <code class="language-plaintext highlighter-rouge">.word 0x2c119c60</code> to refer to the address of the symbol <code class="language-plaintext highlighter-rouge">start</code>).</li>
</ul>

<p>We start the file off with <code class="language-plaintext highlighter-rouge">.section .data.head</code> to tell the assembler to place the following assembly into a ELF section called <code class="language-plaintext highlighter-rouge">.data.head</code>. This allows us to place the data at the start of the final payload as defined in the linker script (described later).</p>

<p>The assembly may contain <code class="language-plaintext highlighter-rouge">.word</code> directives to place hard-coded integers/symbol addresses, or it can contain MIPS instructions. It’s important to be aware that the assembler synthesizes branch delay slots by default, so some MIPS instructions may actually end up being two instructions in the final output.</p>

<h3 id="developing-the-shellcode">Developing the shellcode</h3>

<p>At this point, we can simply define a <code class="language-plaintext highlighter-rouge">start</code> label and write the entire shellcode in MIPS assembly:</p>

<pre><code class="language-gas">.global start
start:
# ...
</code></pre>

<p>At a high-level, our shellcode needs to make the following syscalls:</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">socket</code> to create a TCP socket.</li>
  <li><code class="language-plaintext highlighter-rouge">bind</code> to an address (in our proof-of-concept, we bind to <code class="language-plaintext highlighter-rouge">0.0.0.0:8888</code>).</li>
  <li><code class="language-plaintext highlighter-rouge">listen</code> for connections.</li>
  <li><code class="language-plaintext highlighter-rouge">accept</code> a connection.</li>
  <li><code class="language-plaintext highlighter-rouge">dup2</code> each of file descriptors 0, 1, and 2 to the new connection socket file descriptor.</li>
  <li><code class="language-plaintext highlighter-rouge">execve</code> <code class="language-plaintext highlighter-rouge">/bin/sh -i</code> to actually pop the shell.</li>
</ul>

<p>The process for <a href="https://man7.org/linux/man-pages/man2/syscall.2.html">making a syscall under Linux for MIPS</a> is summarized as follows:</p>

<ol>
  <li>Set <code class="language-plaintext highlighter-rouge">v0</code> to the requested syscall number.</li>
  <li>Up to 4 arguments are passed through registers <code class="language-plaintext highlighter-rouge">a0</code> - <code class="language-plaintext highlighter-rouge">a3</code>.</li>
  <li>Execute the <code class="language-plaintext highlighter-rouge">syscall</code> instruction.</li>
  <li>The return value is stored in <code class="language-plaintext highlighter-rouge">v0</code>. If <code class="language-plaintext highlighter-rouge">a3</code> is non-zero, an error has occurred, and <code class="language-plaintext highlighter-rouge">v0</code> contains the error number.</li>
</ol>

<p>System call numbers can be found in the <a href="https://github.com/torvalds/linux/blob/v2.6.32/arch/mips/include/asm/unistd.h"><code class="language-plaintext highlighter-rouge">unistd.h</code> Linux kernel UAPI header</a>.</p>

<h3 id="developing-the-shellcode-in-c">Developing the shellcode in C</h3>

<p>While handcrafted assembly can be nice and compact, it would be neat if we could develop the shellcode in a higher-level language like C.</p>

<p>For this to work, the C compiler requires that, upon entry to a function, the stack pointer is correctly initialised, and that code calling the C functions obey the MIPS calling convention. Fortunately, our code is being called from the HTTP event handler as if it were a normal C function call, so the execution environment is already amenable to running C. This means our entry point can simply be a normal C function.</p>

<p>The major caveat here is that we mustn’t call any functions in the standard library that may come with our toolchain. We can’t assume that the functions from the toolchain’s standard library will work in the target process, since the functions’ implementations are often tightly coupled to the runtime environment provided by the toolchain’s startup code. To prevent accidentally including unwanted dependencies (e.g. the toolchain’s startup code), code should be compiled with the following flags: <code class="language-plaintext highlighter-rouge">-nostdlib -ffreestanding</code>.</p>

<p>The most straightforward and least-dependencies approach is to implement every single function that we need ourselves. We can perform syscalls using inline assembly, and structure definitions can be declared inline (or with very careful use of the Linux kernel UAPI headers described above).</p>

<p>Alternatively, if memory addresses of functions in the target process address space is known, we can use static function pointers to call functions in libraries that are already loaded in the target process. For example, if the address of <code class="language-plaintext highlighter-rouge">execv</code> is known to be at <code class="language-plaintext highlighter-rouge">0x0000c200</code>, we can define a wrapper function as:</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">static</span> <span class="kr">inline</span> <span class="kt">int</span> <span class="nf">execv</span><span class="p">(</span><span class="kt">char</span> <span class="o">*</span><span class="n">path</span><span class="p">,</span> <span class="kt">char</span> <span class="o">*</span><span class="n">argv</span><span class="p">[])</span> <span class="p">{</span>
    <span class="k">return</span> <span class="p">((</span><span class="kt">int</span> <span class="p">(</span><span class="o">*</span><span class="p">)(</span><span class="kt">char</span> <span class="o">*</span><span class="p">,</span> <span class="kt">char</span> <span class="o">*</span><span class="p">[]))</span><span class="mh">0x0000c200</span><span class="p">)(</span><span class="n">path</span><span class="p">,</span> <span class="n">argv</span><span class="p">);</span>
<span class="p">}</span>
</code></pre></div></div>

<h3 id="making-use-of-linker-scripts">Making use of linker scripts</h3>

<p>We can use linker scripts to control the placement of all the components that will appear in the final payload. We also specify where in memory the start of the payload will be loaded (i.e. <code class="language-plaintext highlighter-rouge">0x2c10e154</code>) so the linker can calculate absolute memory addresses for us correctly.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>SECTIONS
{
	.data 0x2c10e154 : {
		*(.data.head)

		/* ... */
</code></pre></div></div>

<p>The <code class="language-plaintext highlighter-rouge">*(.data.head)</code> line means that the <code class="language-plaintext highlighter-rouge">.data.head</code> section must appear as the first thing in our final payload. Some other sections must be added to support running C code, but their placement is otherwise unimportant in this particular case.</p>

<p>We also discard all unnecessary sections (e.g. automatically generated debug information, or build IDs), since we don’t want them appearing in our final output.</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>	/DISCARD/ : { *(*) }
}
</code></pre></div></div>

<h3 id="testing-the-payload">Testing the payload</h3>

<p>To test the payload without having to perform an entire exploitation cycle, we can compile a very minimal executable containing only the payload that can be run under QEMU user-space emulation on the host: <code class="language-plaintext highlighter-rouge">mips-linux-gnu-gcc -O3 payload.c -e start -nostdlib -ffreestanding -o test</code></p>

<h3 id="previewing-the-final-output">Previewing the final output</h3>

<p>The output of all of our compilation and linking is an ELF file. We can use <code class="language-plaintext highlighter-rouge">mips-linux-gnu-objdump -D input.elf</code> to view the final disassembly of our payload. We should expect that the memory addresses match where we want all of our data and code to be placed in the target process.</p>

<h3 id="dumping-the-raw-memory-image">Dumping the raw memory image</h3>

<p>We can convert our output ELF file into a raw memory image using: <code class="language-plaintext highlighter-rouge">mips-linux-gnu-objcopy -O binary input.elf output.bin</code>.</p>

<h2 id="conclusion">Conclusion</h2>

<p>With our final payload, we can perform the exploit, connect to the socket listener that we opened in the shellcode, and be greeted with a root shell:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>/bin/sh: can't access tty; job control turned off
/etc # busybox id
uid=0(root) gid=0(root)
/etc # 
</code></pre></div></div>]]></content><author><name></name></author><summary type="html"><![CDATA[In the previous post, I described how we can exploit CVE-2026-1668 to gain arbitrary code execution. In this post, I go into the details of building a useful exploit payload.]]></summary></entry><entry><title type="html">Getting root on on TP-Link Smart Switches using CVE-2026-1668 - Part 2</title><link href="https://blog.tangrs.id.au/2026/03/24/exploiting-cve-2026-1668-part-2/" rel="alternate" type="text/html" title="Getting root on on TP-Link Smart Switches using CVE-2026-1668 - Part 2" /><published>2026-03-24T00:00:00+00:00</published><updated>2026-03-24T00:00:00+00:00</updated><id>https://blog.tangrs.id.au/2026/03/24/exploiting-cve-2026-1668-part-2</id><content type="html" xml:base="https://blog.tangrs.id.au/2026/03/24/exploiting-cve-2026-1668-part-2/"><![CDATA[<p>In the <a href="/2026/03/23/exploiting-cve-2026-1668-part-1/">previous post</a>, I described the details of CVE-2026-1668, and how we’re able to obtain an out-of-bounds write by setting a specific value in the <code class="language-plaintext highlighter-rouge">Content-Length</code> header. In this post, we describe how we can use that achieve arbitrary code execution.</p>

<h2 id="http-server-event-loop">HTTP server event loop</h2>

<p>It is first helpful to understand the the high-level architecture of the firmware’s HTTP server.</p>

<p>The server is event-driven and can hold state for up to 16 connections simultaneously (though it appears that it can only serve one at a time). The event loop repeatedly loops over all the active connections and services any that are ready.</p>

<p>A simplified summary of the event-loop looks roughly like the following:</p>

<ol>
  <li>Read all active connection slots and collect socket file descriptors.</li>
  <li>Call <code class="language-plaintext highlighter-rouge">select</code> on the file descriptors with a 5 second timeout.</li>
  <li>Loop over all the active connections slots.</li>
  <li>If the associated socket has activity (as indicated by the results of the <code class="language-plaintext highlighter-rouge">select</code> call), service the request. Otherwise, check if the last activity was too long ago, closing the connection if so.</li>
  <li>If there was an error servicing the request for whatever reason (including timeouts), call the error notification callback function, and close the connection.</li>
</ol>

<p>The fields of the connection state-tracking structure relevant to this exploit are:</p>

<ul>
  <li>Socket file descriptor number</li>
  <li>Unix timestamp of the last activity on this connection</li>
  <li>Enum representing the state of the connection tracking entry (i.e. whether it is active or free)</li>
  <li>Pointer to the error notification callback function</li>
</ul>

<p>Each connection state-tracking entry also has an associated per-connection memory pool for allocating temporary buffers in the HTTP request handler. The memory pool structure immediately follows the associated state-tracking structure in memory.</p>

<p>Both the memory for the connection state-tracking structure and the per-connection memory pool is pre-allocated at init time.</p>

<h2 id="hijacking-the-control-flow">Hijacking the control flow</h2>

<p>The out-of-bounds write happens from within the per-connection memory pool and gives us the ability to overwrite anything in the memory that follows.</p>

<p>The goal here is to overwrite some part of memory that will affect the control flow somehow. The most straightforward way is to look for function pointers, since they let us hijack the control flow to arbitrary locations. Conveniently, the memory that follows the per-connection memory pool contains a connection state-tracking structure, and the most obvious candidate within that structure is the error notification callback function pointer.</p>

<p>We can combine overwriting the function pointer and the last activity timestamp to hijack the control flow. We set the error notification function pointer to the memory location we want to eventually jump to, and the last activity to a timestamp in the past (e.g. 1970-01-01 00:00:00). This represents a timeout condition, causing the error notification function pointer to be called upon the next iteration of the event-loop.</p>

<p>Here is a diagram summarising the memory layout (addresses are in ascending order):</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>          ...
~                     ~
+---------------------+
| Connection State #2 |
| |-&gt; last_activity   |
| |-&gt; error_notif_cb  |
+---------------------+
| Allocator  Metadata |
+---------------------+
|    Connection #2    |
|   Request Handler   | -+ [ Start of out-of-bounds write ]
|     Memory Pool     |  |
+---------------------+  |
| Allocator  Metadata |  |
+---------------------+  |
| Connection State #1 |  |
| |-&gt; last_activity   |  |
| |-&gt; error_notif_cb  |  |
+---------------------+ -+ [ End of out-of-bounds write   ]
| Allocator  Metadata |
+---------------------+
|    Connection #1    |
|   Request Handler   |
|     Memory Pool     |
+---------------------+
~                     ~
          ...
</code></pre></div></div>

<h2 id="putting-it-all-together">Putting it all together</h2>

<p>Interestingly, connection state-tracking entries appear to be allocated in reverse order of memory (that is, older connections use entries at higher memory addresses compared to newer connections). Unfortunately, it is currently unclear to me why this is the case. The code for the event handling loop has been heavily optimized by the compiler, making the logic difficult to follow.</p>

<p>In practice, this does not matter because the placement and the values of the connection state-tracking entries on new connections is highly deterministic (at least on a fresh boot). Thus, I did not feel the need to accurately reason about the event-handling logic for the purposes of making this exploit work.</p>

<p>To set up the target memory in a way that lets us hijack the control flow, we first open a connection to reserve a connection state-tracking entry (connection #1 in the diagram below). Note that this is merely acts as a placeholder and we don’t actually write anything to it.</p>

<p>We then open a second connection (connection #2 in the diagram below), which is allocated the entry immediately before connection #1 in memory, and then write a carefully crafted payload. This overwrites the values in the connection #1 state-tracking structure with values that we need in order to hijack the control flow.</p>

<p>Once the HTTP handler on connection #2 returns (e.g. through a premature connection closure), the event loop will find that connection #1 has “timed out”, and calls the error notification callback (whose address we just overwrote).</p>

<p>Now that we have control over the program counter, we can redirect execution to any executable region in memory.</p>

<h2 id="but-where">But where?</h2>

<p>Let’s see if there are any candidate executable memory regions that we can usefully redirect execution to.</p>

<p>We’re able to dump a list of memory mappings and their associated permission bits using GDB. Here is the output with the less interesting parts elided:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>(gdb) info proc mappings
process 257
Mapped address spaces:

Start Addr End Addr   Size       Offset     Perms File 
0x00400000 0x0047f000 0x7f000    0x0        r-xp  /tplink/image/usrImage/app/sbin/httpd 
0x0048e000 0x00498000 0xa000     0x7e000    rw-p  /tplink/image/usrImage/app/sbin/httpd 
0x00498000 0x004d2000 0x3a000    0x0        rwxp  [heap] 
0x2aaa8000 0x2aaaf000 0x7000     0x0        r-xp  /lib/ld-uClibc-0.9.33.so
...  
0x2ba19000 0x2c291000 0x878000   0x0        rw-p
...
0x7fa99000 0x7faae000 0x15000    0x0        rwxp  [stack] 
0x7fff7000 0x7fff8000 0x1000     0x0        r-xp  [vdso] 
</code></pre></div></div>

<p>All of the memory associated with HTTP request handling, and connection metadata tracking is located in the <code class="language-plaintext highlighter-rouge">0x2ba19000</code>-<code class="language-plaintext highlighter-rouge">0x2c291000</code> region, which, unfortunately, does not have the execute permission bit set. This is rather unfortunate because it seems like we can’t simply load in shellcode along with the payload, and jump directly to it.</p>

<p>I was considering employing some sort of <a href="https://en.wikipedia.org/wiki/Return-oriented_programming">return-oriented programming</a> to get around this. Or, find a way to get shellcode loaded somewhere predictable in the heap or stack (which for some reason, <em>has</em> execute permissions).</p>

<h2 id="an-amusing-note-on-memory-permission-bits-in-mips">An amusing note on memory permission bits in MIPS</h2>

<p>On a hunch, I decided to test what would happen if I <em>did</em> attempt to execute code in a non-executable memory region. Surprisingly, it worked!</p>

<p>My guess, which seemingly turned out to be correct, was that the 4KEc MIPS core on the SoC does not implement the <a href="https://en.wikipedia.org/wiki/NX_bit">Inhibit Execute</a> bit. The 4KEc MIPS core implements an older revision of the ISA specification without the IX bit.</p>

<p>Amusingly, this means that there is literally no hardware mechanism for enforcing the execute memory permission bit. For all intents and purposes, we can simply ignore it, which <em>greatly</em> simplifies exploitation.</p>

<h2 id="conclusion">Conclusion</h2>

<p>We have now turned an out-of-bounds write vulnerability into a primitive that allows us to gain arbitrary code execution. In <a href="/2026/04/06/exploiting-cve-2026-1668-part-3/">the next post</a>, we explore some ways of crafting a useful exploit payload.</p>

<hr />

<h3 id="notes">Notes</h3>

<p>It’s worth mentioning that modern hardening mechanisms would have made exploitation <em>much</em> less straightforward (perhaps even impossible):</p>

<ul>
  <li>Almost all commonly used modern CPU architectures have support for preventing executing code in non-executable memory regions.
    <ul>
      <li>We would have had to find some other way to obtain arbitrary code execution.</li>
    </ul>
  </li>
  <li>Modern compilers and operating systems employ <a href="https://en.wikipedia.org/wiki/Address_space_layout_randomization">address space layout randomization</a>.
    <ul>
      <li>This would have made crafting the payload much more difficult, since we wouldn’t know exactly where our payload was loaded in memory.</li>
    </ul>
  </li>
</ul>]]></content><author><name></name></author><summary type="html"><![CDATA[In the previous post, I described the details of CVE-2026-1668, and how we’re able to obtain an out-of-bounds write by setting a specific value in the Content-Length header. In this post, we describe how we can use that achieve arbitrary code execution.]]></summary></entry><entry><title type="html">Getting root on on TP-Link Smart Switches using CVE-2026-1668 - Part 1</title><link href="https://blog.tangrs.id.au/2026/03/23/exploiting-cve-2026-1668-part-1/" rel="alternate" type="text/html" title="Getting root on on TP-Link Smart Switches using CVE-2026-1668 - Part 1" /><published>2026-03-23T00:00:00+00:00</published><updated>2026-03-23T00:00:00+00:00</updated><id>https://blog.tangrs.id.au/2026/03/23/exploiting-cve-2026-1668-part-1</id><content type="html" xml:base="https://blog.tangrs.id.au/2026/03/23/exploiting-cve-2026-1668-part-1/"><![CDATA[<p>In late 2025, I discovered a vulnerability in some TP-Link Smart Switches that could be exploited to obtain unauthenticated remote code execution as root (<a href="https://www.cve.org/CVERecord?id=CVE-2026-1668">CVE-2026-1668</a>).</p>

<p>This was reported to security@tp-link.com, and in mid-March 2026, a fixed version of the firmware was made available. TP-Link has also published a <a href="https://support.omadanetworks.com/us/document/118794/">security advisory</a>, recommending users to update their firmware on affected devices. If you have an affected device, I recommend you update the firmware immediately.</p>

<p>It is now 90+30 days after the initial report and a fix is available. It’s time to discuss the vulnerability in more detail.</p>

<h2 id="the-vulnerability">The vulnerability</h2>

<p>The vulnerability exists in the <code class="language-plaintext highlighter-rouge">httpJsonPost</code> function of the <code class="language-plaintext highlighter-rouge">httpd</code> binary, which reads and returns the body of a POST request as a C string. Here is the relevant excerpt of decompiler output from Ghidra that shows the logic:</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">pcVar1</span> <span class="o">=</span> <span class="p">(</span><span class="kt">char</span> <span class="o">*</span><span class="p">)</span><span class="n">httpMimeHdrGet</span><span class="p">(</span><span class="n">req</span><span class="p">,</span><span class="mi">0</span><span class="p">,</span><span class="s">"Content-Length"</span><span class="p">);</span>
<span class="n">contentLength</span> <span class="o">=</span> <span class="n">strtoul</span><span class="p">(</span><span class="n">pcVar1</span><span class="p">,(</span><span class="kt">char</span> <span class="o">**</span><span class="p">)</span><span class="mh">0x0</span><span class="p">,</span><span class="mi">0</span><span class="p">);</span>
<span class="k">if</span> <span class="p">(</span><span class="n">contentLength</span> <span class="o">!=</span> <span class="mi">0</span><span class="p">)</span> <span class="p">{</span>
  <span class="n">p</span> <span class="o">=</span> <span class="p">(</span><span class="n">mem_pool_t</span> <span class="o">*</span><span class="p">)</span><span class="n">httpReqMemPartIdGet</span><span class="p">(</span><span class="n">req</span><span class="p">);</span>
  <span class="n">buf</span> <span class="o">=</span> <span class="p">(</span><span class="kt">char</span> <span class="o">*</span><span class="p">)</span><span class="n">memPoolAlloc</span><span class="p">(</span><span class="n">p</span><span class="p">,</span><span class="n">contentLength</span> <span class="o">+</span> <span class="mi">1</span><span class="p">);</span>
  <span class="k">if</span> <span class="p">(</span><span class="n">buf</span> <span class="o">==</span> <span class="p">(</span><span class="kt">char</span> <span class="o">*</span><span class="p">)</span><span class="mh">0x0</span><span class="p">)</span> <span class="p">{</span>
    <span class="n">wmError</span><span class="p">(</span><span class="o">-</span><span class="mi">100</span><span class="p">,</span><span class="s">"httpJsonPost: unable to allocate mem for entity"</span><span class="p">);</span>
    <span class="k">return</span> <span class="o">-</span><span class="mi">1</span><span class="p">;</span>
  <span class="p">}</span>
  <span class="n">n</span> <span class="o">=</span> <span class="mi">0</span><span class="p">;</span>
  <span class="n">i</span> <span class="o">=</span> <span class="mi">0</span><span class="p">;</span>
  <span class="k">do</span> <span class="p">{</span>
    <span class="n">readBytes</span> <span class="o">=</span> <span class="n">httpBlockRead</span><span class="p">(</span><span class="n">req</span><span class="p">,</span><span class="n">buf</span> <span class="o">+</span> <span class="n">n</span><span class="p">,</span><span class="n">contentLength</span> <span class="o">-</span> <span class="n">n</span><span class="p">);</span>
    <span class="n">i</span> <span class="o">=</span> <span class="n">i</span> <span class="o">+</span> <span class="mi">1</span><span class="p">;</span>
    <span class="n">n</span> <span class="o">=</span> <span class="n">n</span> <span class="o">+</span> <span class="n">readBytes</span><span class="p">;</span>
    <span class="k">if</span> <span class="p">((</span><span class="n">readBytes</span> <span class="o">==</span> <span class="o">-</span><span class="mi">1</span><span class="p">)</span> <span class="o">||</span> <span class="p">(</span><span class="n">contentLength</span> <span class="o">==</span> <span class="n">n</span><span class="p">))</span> <span class="k">break</span><span class="p">;</span>
    <span class="n">usleep</span><span class="p">(</span><span class="mi">2000</span><span class="p">);</span>
  <span class="p">}</span> <span class="k">while</span> <span class="p">(</span><span class="n">i</span> <span class="o">!=</span> <span class="mh">0x14</span><span class="p">);</span>
  <span class="n">buf</span><span class="p">[</span><span class="n">contentLength</span><span class="p">]</span> <span class="o">=</span> <span class="sc">'\0'</span><span class="p">;</span>
  <span class="k">if</span> <span class="p">(</span><span class="n">out</span> <span class="o">!=</span> <span class="p">(</span><span class="kt">char</span> <span class="o">**</span><span class="p">)</span><span class="mh">0x0</span><span class="p">)</span> <span class="p">{</span>
    <span class="o">*</span><span class="n">out</span> <span class="o">=</span> <span class="n">buf</span><span class="p">;</span>
    <span class="k">return</span> <span class="mi">0</span><span class="p">;</span>
  <span class="p">}</span>
<span class="p">}</span>
</code></pre></div></div>

<p>At a high-level, the logic does the following:</p>

<ol>
  <li>Reads the <code class="language-plaintext highlighter-rouge">Content-Length</code> header value as a string.</li>
  <li>Use <code class="language-plaintext highlighter-rouge">strtoul</code> to parse the string into <code class="language-plaintext highlighter-rouge">contentLength</code>, as an unsigned integer.</li>
  <li>Check whether <code class="language-plaintext highlighter-rouge">contentLength</code> is zero (i.e. the request included a correctly-formatted, non-zero integer as the Content-Length).</li>
  <li>Allocate <code class="language-plaintext highlighter-rouge">contentLength + 1</code> bytes of memory to store the request + null byte to terminate the buffer into a C string.</li>
  <li>Check whether the memory allocation failed.</li>
  <li>Read up to <code class="language-plaintext highlighter-rouge">contentLength</code> bytes of data into the allocated buffer.</li>
</ol>

<p>The problem with this logic is that it does not take into account of integer overflow. If <code class="language-plaintext highlighter-rouge">contentLength</code> is set to 4294967295, it passes the length check, but overflows to zero once incremented. Thus, <code class="language-plaintext highlighter-rouge">memPoolAlloc</code> is actually called with an argument of zero, and the implementation happily returns a pointer to a zero-sized block of memory. At this point, <em>any</em> write to the returned pointer is an out-of-bounds write.</p>

<p>For non-HTTPS requests, <code class="language-plaintext highlighter-rouge">httpBlockRead</code> is essentially a wrapper around a <code class="language-plaintext highlighter-rouge">read</code> syscall. On the Linux kernel version running on the device, the <code class="language-plaintext highlighter-rouge">read</code> syscall is happy to take a large size (i.e. 4294967295) parameter, and just do short reads (we do not need to actually send 4294967295 bytes of payload). FWIW, this did not work when I tested this under QEMU emulation - instead, <code class="language-plaintext highlighter-rouge">read</code> just immediately returns an EFAULT error.</p>

<p>Unfortunately, on HTTPS requests, <code class="language-plaintext highlighter-rouge">httpBlockRead</code> ends up calling the OpenSSL <code class="language-plaintext highlighter-rouge">SSL_Read</code> function, which treats the size parameter as a signed integer and fails the early length-check for negative sizes (because 4294967295 in interpreted as -1). Because of this, I have not found a way to trigger this vulnerability when using HTTPS. However, this is a moot point because the firmware still responds to HTTP API requests on a default installation of the latest firmware at the time.</p>

<h3 id="the-fix">The fix</h3>

<p>This vulnerability was fixed by improving the length checking. Previously, it was simply a comparison for zero, allowing for overflow when evaluating <code class="language-plaintext highlighter-rouge">contentLength + 1</code>:</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">if</span> <span class="p">(</span><span class="n">contentLength</span> <span class="o">!=</span> <span class="mi">0</span><span class="p">)</span>
</code></pre></div></div>

<p>The improved logic now checks that the result of <code class="language-plaintext highlighter-rouge">contentLength + 1</code> will never exceed 0x20000:</p>

<div class="language-c highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">if</span> <span class="p">(</span><span class="n">contentLength</span> <span class="o">-</span> <span class="mi">1</span> <span class="o">&lt;</span> <span class="mh">0x20000</span><span class="p">)</span>
</code></pre></div></div>

<p>Having looked at the assembly code, this is indeed an unsigned integer comparison, so the check should work even if <code class="language-plaintext highlighter-rouge">contentLength - 1</code> underflows. The comparison will be against 0xFFFFFFFF, which is greater than 0x20000, failing the check as intended.</p>

<p>As far as I can tell, this improved length checking is sufficient for patching the vulnerability.</p>

<h2 id="triggering-the-vulnerability">Triggering the vulnerability</h2>

<p>The most convenient way to trigger the vulnerable <code class="language-plaintext highlighter-rouge">httpJsonPost</code> function is via the <code class="language-plaintext highlighter-rouge">/data/login.json</code> HTTP endpoint because it does not require any authentication, and is always available.</p>

<p>We can send the following HTTP request to trigger the vulnerability:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>POST /data/login.json HTTP/1.1
Content-Type: application/json
Content-Length: 4294967295
</code></pre></div></div>

<p>Any data we include in the body of the POST request can be used to overwrite whatever happens to be in memory below the buffer.</p>

<p>In the <a href="/2026/03/24/exploiting-cve-2026-1668-part-2/">next post</a>, we will look at how we can exploit this vulnerability to gain arbitrary code execution.</p>

<hr />

<h3 id="disclosure-timeline">Disclosure timeline</h3>

<ul>
  <li>2025-11-22: Vulnerability reported to security@tp-link.com.</li>
  <li>2025-11-26: TP-Link acknowledged receipt of the report, pending initial triage.</li>
  <li>2025-12-23: Sent a follow-up email, asking for updates.</li>
  <li>2026-01-10: TP-Link acknowledged the vulnerability, pending verification and remediation.</li>
  <li>2026-01-15: Sent a follow-up email, confirming the vulnerability is still exploitable on the latest firmware, and asking for an update on remediation.</li>
  <li>2026-01-26: Sent another follow-up asking for updates, after no reply.</li>
  <li>2026-01-28: TP-Link claimed the vulnerability has been addressed in their development build.</li>
  <li>2026-01-29: TP-Link sent a pre-release firmware image for verifying that the vulnerability has been sufficiently addressed.</li>
  <li>2026-01-29: Sent confirmation that the vulnerability appeared to be sufficiently addressed.</li>
  <li>2026-01-30: Vulnerability assigned to CVE-2026-1668.</li>
  <li>2026-02-12: TP-Link asked for an extension to the disclosure deadline.</li>
  <li>2026-02-12: Granted extension until 2026-03-16.</li>
  <li>2026-02-20: 90 days elapsed since initial vulnerability report.</li>
  <li>2026-03-14: TP-Link made fixed firmwares public, and published security advisory.</li>
  <li>2026-03-22: 90+30 days elapsed since initial vulnerability report.</li>
</ul>

<h3 id="similar-bugs-in-other-tp-link-devices">Similar bugs in other TP-Link devices</h3>

<ul>
  <li><a href="https://nvd.nist.gov/vuln/detail/CVE-2026-0918">CVE-2026-0918</a> seems to describe a similar bug in Tapo C220 and C520WS devices.
    <ul>
      <li><a href="https://www.tp-link.com/us/support/faq/4923/">TP-Link Security Advisory</a></li>
    </ul>
  </li>
  <li><a href="https://nvd.nist.gov/vuln/detail/CVE-2025-14299">CVE-2025-14299</a> describes a similar bug in Tapo C200 devices.
    <ul>
      <li><a href="https://www.evilsocket.net/2025/12/18/TP-Link-Tapo-C200-Hardcoded-Keys-Buffer-Overflows-and-Privacy-in-the-Era-of-AI-Assisted-Reverse-Engineering/">Blog post by evilsocket</a>.</li>
      <li><a href="https://www.tp-link.com/us/support/faq/4849/">TP-Link Security Advisory</a></li>
    </ul>
  </li>
</ul>]]></content><author><name></name></author><summary type="html"><![CDATA[In late 2025, I discovered a vulnerability in some TP-Link Smart Switches that could be exploited to obtain unauthenticated remote code execution as root (CVE-2026-1668).]]></summary></entry><entry><title type="html">Low-trust ZFS Replication on TrueNAS</title><link href="https://blog.tangrs.id.au/2025/12/22/low-trust-zfs-replication-on-truenas/" rel="alternate" type="text/html" title="Low-trust ZFS Replication on TrueNAS" /><published>2025-12-22T00:00:00+00:00</published><updated>2025-12-22T00:00:00+00:00</updated><id>https://blog.tangrs.id.au/2025/12/22/low-trust-zfs-replication-on-truenas</id><content type="html" xml:base="https://blog.tangrs.id.au/2025/12/22/low-trust-zfs-replication-on-truenas/"><![CDATA[<p>TrueNAS’s snapshot replication functionality is useful for implementing off-site backups. I currently use this functionality to perform a two-way cross-backup of two TrueNAS installations. Unfortunately, the current version of TrueNAS doesn’t seem to provide many options for building strong protections against local compromise (e.g. ransomware attacks that target TrueNAS) having the ability to compromise backups.</p>

<p>The core requirement I have for my personal data is: total compromise of a single TrueNAS machine should not be able to compromise previous backups stored on the other TrueNAS machine.</p>

<p>In practice, I belive this means:</p>

<ul>
  <li>Snapshots must be <em>pulled</em> by the backup machine, rather than <em>pushed</em> by the target.
    <ul>
      <li>This prevents a potentially compromised target from compromising backups on the backup machine.</li>
    </ul>
  </li>
  <li>The credentials used by the backup machine must not have privileges that exceed what is required (i.e. no write access on the target).
    <ul>
      <li>This prevents a potentially compromised backup machine from compromising data on the target.</li>
    </ul>
  </li>
</ul>

<p>TrueNAS offers functionality for implementing the former and it is built into the web UI.</p>

<p>However, the default snapshot replication functionality offered by TrueNAS typically requires the use of a privileged user on the target (presumably in order to run <code class="language-plaintext highlighter-rouge">zfs</code> commands). The best built-in mitigation offered seems to be to use an otherwise-unprivileged user that has sudo access limited to the <code class="language-plaintext highlighter-rouge">zfs</code> command. Unfortunately, still seems too broad of a privilege, since it doesn’t preclude write-access.</p>

<p>The good news is that TrueNAS does seem to bless the use of <code class="language-plaintext highlighter-rouge">zfs allow</code> commands to implement finer-grained controls (it is mentioned in the tooltip for the “Use Sudo For ZFS Commands” option), despite the warnings to the contrary shown when you open a shell. The bad news is that there doesn’t seem to be much clear guidance in the TrueNAS manuals on how to implement this.</p>

<p>Here is how I ended up implementing low-trust snapshot replication:</p>

<p>Create an unprivileged backup user on the target:</p>

<ul>
  <li>It should not be a member of any groups, or have an SMB account.</li>
  <li>It should have a real shell (i.e. not <code class="language-plaintext highlighter-rouge">nologin</code>).</li>
  <li>It should have a home directory somewhere (in order to store a <code class="language-plaintext highlighter-rouge">~/.ssh/authorized_keys</code> file).</li>
  <li><code class="language-plaintext highlighter-rouge">sudo</code> access should <em>not</em> be allowed (not even for <code class="language-plaintext highlighter-rouge">zfs</code>).</li>
</ul>

<p>Grant the backup user privileges to send snapshots:</p>

<p>With an admin account, open a shell and use the following command:</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>sudo zfs allow &lt;user&gt; send,hold
</code></pre></div></div>

<p>Add backup credentials on the backup machine:</p>

<ol>
  <li>On the backup machine, navigate to Credentials &gt; Backup Credentials.</li>
  <li>Create an SSH keypair.
    <ul>
      <li>Add the public key to the list of Authorized Keys for the backup user on the target.</li>
    </ul>
  </li>
  <li>Create a new SSH connection.
    <ul>
      <li>Change Setup Method to manual.</li>
      <li>Populate the fields, using the backup user on the target as the Username.</li>
      <li>Select the Private Key created previously.</li>
      <li>Populate the SSH host key of the target.
        <ul>
          <li>This is the output of <code class="language-plaintext highlighter-rouge">cat /etc/ssh/ssh_host_*.pub</code> on the target.</li>
          <li>If the network between the backup machine and target is trusted, the “Discover Remote Host Key” button can also be used for convenience.</li>
        </ul>
      </li>
    </ul>
  </li>
  <li>Save.</li>
</ol>

<p>Finally, when setting up a replication task on the backup machine, use the SSH connection established previously. Use “On a different system” for the source location (i.e. a PULL configuration), and do not accept the use of <code class="language-plaintext highlighter-rouge">sudo</code> for running ZFS commands.</p>]]></content><author><name></name></author><summary type="html"><![CDATA[TrueNAS’s snapshot replication functionality is useful for implementing off-site backups. I currently use this functionality to perform a two-way cross-backup of two TrueNAS installations. Unfortunately, the current version of TrueNAS doesn’t seem to provide many options for building strong protections against local compromise (e.g. ransomware attacks that target TrueNAS) having the ability to compromise backups.]]></summary></entry><entry><title type="html">Verifying TP-Link Smart Switch Firmware Signatures</title><link href="https://blog.tangrs.id.au/2025/12/07/verifying-tplink-smart-switch-firmware-signatures/" rel="alternate" type="text/html" title="Verifying TP-Link Smart Switch Firmware Signatures" /><published>2025-12-07T00:00:00+00:00</published><updated>2025-12-07T00:00:00+00:00</updated><id>https://blog.tangrs.id.au/2025/12/07/verifying-tplink-smart-switch-firmware-signatures</id><content type="html" xml:base="https://blog.tangrs.id.au/2025/12/07/verifying-tplink-smart-switch-firmware-signatures/"><![CDATA[<p>In a previous post, I described the <a href="/2025/09/22/decrypting-tplink-smart-switch-firmware/">firmware encryption</a> for some TP-Link Smart Switches. At the end of the post, I alluded to the fact that TP-Link does sign and verify firmware signatures, but did not dig deeper at the time.</p>

<p>Recently, I have investigated into how the signature verification works exactly.</p>

<p>From looking at some code in the <a href="https://github.com/watchfulip/tp-link-decrypt/">tp-link-decrypt project</a> on Github, and reverse engineering the firmware code responsible for verification, we indeed find that the final 128 bytes at the end of the firmware image is an RSA signature.</p>

<p>The signature is verified against an RSA public key that is hard-coded into the firmware as a base64 string:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>BgIAAACkAABSU0ExAAQAAAEAAQBhVXK3wF79A6cXXFu0Y0wKz0dPQWi2dWPE7p8eY9e6PAqc5BBT
QPxi2/N1OotrUN11Q6cBXA0gmflRusUiJtdARng43tSWz2pZueskCC5kH9/+1/ACi2ZY1WlK5TVu5B
h0YCzAfvlmsbuPjk/W4S3Jco+ISDOrpF5wwuxlCHI2vQ==
</code></pre></div></div>

<p>The key is encoded in Microsoft’s <a href="https://learn.microsoft.com/en-us/windows/win32/seccrypto/rsa-schannel-key-blobs#public-key-blobs"><code class="language-plaintext highlighter-rouge">PUBLICKEYBLOB</code></a> format. <code class="language-plaintext highlighter-rouge">openssl</code> supports decoding such keys:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code> % echo 'BgIAAACkAABSU0ExAAQAAAEAAQBhVXK3wF79A6cXXFu0Y0wKz0dPQWi2dWPE7p8eY9e6PAqc5BBT
QPxi2/N1OotrUN11Q6cBXA0gmflRusUiJtdARng43tSWz2pZueskCC5kH9/+1/ACi2ZY1WlK5TVu5B
h0YCzAfvlmsbuPjk/W4S3Jco+ISDOrpF5wwuxlCHI2vQ==' |\
  base64 -d |\
  openssl rsa -pubin -text
Public-Key: (1024 bit)
Modulus:
  00:bd:36:72:08:65:ec:c2:70:5e:a4:ab:33:48:88:
  8f:72:c9:2d:e1:d6:4f:8e:8f:bb:b1:66:f9:7e:c0:
  2c:60:74:18:e4:6e:35:e5:4a:69:d5:58:66:8b:02:
  f0:d7:fe:df:1f:64:2e:08:24:eb:b9:59:6a:cf:96:
  d4:de:38:78:46:40:d7:26:22:c5:ba:51:f9:99:20:
  0d:5c:01:a7:43:75:dd:50:6b:8b:3a:75:f3:db:62:
  fc:40:53:10:e4:9c:0a:3c:ba:d7:63:1e:9f:ee:c4:
  63:75:b6:68:41:4f:47:cf:0a:4c:63:b4:5b:5c:17:
  a7:03:fd:5e:c0:b7:72:55:61
Exponent: 65537 (0x10001)
writing RSA key
-----BEGIN PUBLIC KEY-----
MIGfMA0GCSqGSIb3DQEBAQUAA4GNADCBiQKBgQC9NnIIZezCcF6kqzNIiI9yyS3h
1k+Oj7uxZvl+wCxgdBjkbjXlSmnVWGaLAvDX/t8fZC4IJOu5WWrPltTeOHhGQNcm
IsW6UfmZIA1cAadDdd1Qa4s6dfPbYvxAUxDknAo8utdjHp/uxGN1tmhBT0fPCkxj
tFtcF6cD/V7At3JVYQIDAQAB
-----END PUBLIC KEY-----
</code></pre></div></div>

<p>The code at the <a href="https://github.com/watchfulip/tp-link-decrypt/blob/main/src/rsa_verify/rsaVerify.c">tp-link-decrypt</a> seems to suggest a bespoke signature encoding scheme. However, upon closer inspection, the algorithm described is simply the <a href="https://datatracker.ietf.org/doc/html/rfc3447#section-9.2">PKCS#1v1.5 encoding scheme</a>, specifically the sha1WithRSAEncryption variant.</p>

<p>The data that is being signed is actually the MD5 hash of the (encrypted) firmware image bytes (without including the signature at the end). It’s not clear why TP-Link chose to sign a MD5 hash (which is then hashed again using SHA1 as part of the RSA signature algorithm), instead of just signing the firmware image itself.</p>

<p>Yet, even knowing the above, my first attempt at re-implementing the signature verification routine in Golang fails. Here’s a self-contained test case to demonstrate:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>func TestVerifySignature(t *testing.T) {
  pub := &amp;rsa.PublicKey{
    N: big.NewInt(0).SetBytes([]byte{
      0xbd, 0x36, 0x72, 0x08, 0x65, 0xec, 0xc2, 0x70, 0x5e, 0xa4, 0xab, 0x33, 0x48, 0x88, 0x8f, 0x72,
      0xc9, 0x2d, 0xe1, 0xd6, 0x4f, 0x8e, 0x8f, 0xbb, 0xb1, 0x66, 0xf9, 0x7e, 0xc0, 0x2c, 0x60, 0x74,
      0x18, 0xe4, 0x6e, 0x35, 0xe5, 0x4a, 0x69, 0xd5, 0x58, 0x66, 0x8b, 0x02, 0xf0, 0xd7, 0xfe, 0xdf,
      0x1f, 0x64, 0x2e, 0x08, 0x24, 0xeb, 0xb9, 0x59, 0x6a, 0xcf, 0x96, 0xd4, 0xde, 0x38, 0x78, 0x46,
      0x40, 0xd7, 0x26, 0x22, 0xc5, 0xba, 0x51, 0xf9, 0x99, 0x20, 0x0d, 0x5c, 0x01, 0xa7, 0x43, 0x75,
      0xdd, 0x50, 0x6b, 0x8b, 0x3a, 0x75, 0xf3, 0xdb, 0x62, 0xfc, 0x40, 0x53, 0x10, 0xe4, 0x9c, 0x0a,
      0x3c, 0xba, 0xd7, 0x63, 0x1e, 0x9f, 0xee, 0xc4, 0x63, 0x75, 0xb6, 0x68, 0x41, 0x4f, 0x47, 0xcf,
      0x0a, 0x4c, 0x63, 0xb4, 0x5b, 0x5c, 0x17, 0xa7, 0x03, 0xfd, 0x5e, 0xc0, 0xb7, 0x72, 0x55, 0x61,
    }),
    E: 0x10001,
  }
  md5sum := []byte{0x6e, 0x47, 0xb8, 0x83, 0x4c, 0x9c, 0x0b, 0x61, 0x51, 0x1f, 0x13, 0x0d, 0x88, 0x8f, 0xd3, 0x3f}
  sig := []byte{
    0xf1, 0x29, 0x1d, 0xae, 0x71, 0xf0, 0xd3, 0x47, 0x3b, 0x4b, 0x26, 0xf4, 0x4f, 0x0c, 0x75, 0xc1,
    0x19, 0xa1, 0x8e, 0x04, 0x1b, 0x64, 0xe1, 0x2f, 0x50, 0xe2, 0x5a, 0x6e, 0x58, 0xda, 0x12, 0x42,
    0x91, 0x0f, 0x33, 0xa1, 0xa8, 0x4d, 0xd7, 0xd4, 0x2e, 0xac, 0xac, 0x92, 0xf4, 0x1f, 0x39, 0x8e,
    0xc3, 0x3c, 0xb7, 0xe0, 0x2a, 0x0d, 0x84, 0xed, 0xd0, 0xbb, 0x7a, 0x32, 0xed, 0xb5, 0xf8, 0x33,
    0x9a, 0xdd, 0x9b, 0x0e, 0x66, 0x1a, 0x90, 0xd2, 0xf4, 0xbb, 0x83, 0x72, 0x7e, 0x71, 0xc5, 0x1a,
    0xcf, 0x1e, 0x0a, 0x44, 0x56, 0x54, 0x33, 0xbd, 0xe8, 0x1c, 0xce, 0x61, 0x74, 0xbb, 0x08, 0xd6,
    0xb0, 0x7a, 0xda, 0x8d, 0x89, 0x60, 0xa7, 0x14, 0xb0, 0xb2, 0x30, 0xf0, 0xc4, 0xd5, 0x5c, 0x80,
    0xca, 0x10, 0xc5, 0x29, 0x7f, 0x83, 0x6a, 0xfc, 0x74, 0x34, 0xb1, 0x10, 0xc2, 0xd6, 0x08, 0x30,
  }

  hash := sha1.Sum(md5sum[:])
  if err := rsa.VerifyPKCS1v15(pub, crypto.SHA1, hash[:], sig); err != nil {
    t.Errorf("VerifyPKCS1v15(...): err = %v, want nil", err)
  }
}
</code></pre></div></div>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>VerifyPKCS1v15(...): err = crypto/rsa: verification error, want nil
</code></pre></div></div>

<p>It turns out, for whatever reason, the firmware (and the code in the tp-link-decrypt project) reverses the bytes of the signature before attempting verification. It’s unclear to me whether this is a normal part of validating RSA signatures, but it does seem odd to me. My guess is that the signature was generated by software that uses little-endian representation of integers, whereas many other RSA libraries use big-endian representations. This is consistent with the fact that Microsoft’s <code class="language-plaintext highlighter-rouge">PUBLICKEYBLOB</code> stores the modulus in little-endian.</p>

<p>Adding a <code class="language-plaintext highlighter-rouge">slices.Reverse(sig)</code> call to the above code makes the signature verification pass without issues.</p>

<h2 id="summary">Summary</h2>

<p>To perform signature verification on the firmware image:</p>

<ol>
  <li>Split the firmare image into the data (the first <code class="language-plaintext highlighter-rouge">total_length - 128</code> bytes) and signature (the last 128 bytes).</li>
  <li>Calculate the MD5 hash of the data.</li>
  <li>Reverse the ordering of the bytes of the signature.</li>
  <li>Use the PKCS#1v1.5 sha1WithRSAEncryption signature algorithm to verify the signature against the MD5 hash of the data.</li>
</ol>]]></content><author><name></name></author><summary type="html"><![CDATA[In a previous post, I described the firmware encryption for some TP-Link Smart Switches. At the end of the post, I alluded to the fact that TP-Link does sign and verify firmware signatures, but did not dig deeper at the time.]]></summary></entry><entry><title type="html">Reverse engineering PoE on the TL-SG2008P V3 firmware - Part 2</title><link href="https://blog.tangrs.id.au/2025/10/05/reverse-engineering-poe-tl-sg2008p-v3-part-2/" rel="alternate" type="text/html" title="Reverse engineering PoE on the TL-SG2008P V3 firmware - Part 2" /><published>2025-10-05T00:00:00+00:00</published><updated>2025-10-05T00:00:00+00:00</updated><id>https://blog.tangrs.id.au/2025/10/05/reverse-engineering-poe-tl-sg2008p-v3-part-2</id><content type="html" xml:base="https://blog.tangrs.id.au/2025/10/05/reverse-engineering-poe-tl-sg2008p-v3-part-2/"><![CDATA[<p>In my <a href="/2025/09/30/reverse-engineering-poe-tl-sg2008p-v3-part-1/">previous post</a>, I wrote about how I obtained root on the stock firmware of my switch to try to figure out how the stock firmware was implementing per-port power limits. The next step was to actually perform the introspection into what the stock firmware was doing.</p>

<h2 id="first-attempt-attaching-a-debugger-on-the-system-binary">First attempt: attaching a debugger on the system binary</h2>

<p>My first attempt was to get GDB working so I could set breakpoints and see exactly what the system binary was doing regarding PoE.</p>

<p>More specifically, I wanted to get <code class="language-plaintext highlighter-rouge">gdbserver</code> working on the target and perform debugging remotely. <code class="language-plaintext highlighter-rouge">gdbserver</code> has fewer dependencies and should be easier to cross-compile. The frontend of <code class="language-plaintext highlighter-rouge">gdb</code> can run on my host computer.</p>

<p>Even with its fewer depedencies, compiling <code class="language-plaintext highlighter-rouge">gdbserver</code> wasn’t quite as straightforward as I hoped. The toolchain included in TP-Link’s GPL source code release was quite old, and didn’t support many of the newer compiler features that the newer versions of GDB requires at build-time. To work around this, I compiled the last version of GDB before C++11 support was made mandatory (which turned out to be version 7.12 - about 9 years old at time of writing). I also had to separately compile a copy of <code class="language-plaintext highlighter-rouge">gdb</code> that supported MIPS for my host computer, since the precompiled <code class="language-plaintext highlighter-rouge">gdb</code> binary that came with TP-Link’s toolchain required a bunch of 32-bit libraries that my version of Debian no longer packages.</p>

<p>After compiling, I scp’d <code class="language-plaintext highlighter-rouge">gdbserver</code> onto the switch, and attempted to attach it to the main system binary. Unfortunately, for whatever reason, it seems the stock firmware seems to freeze up if the main system binary gets paused/stopped, even for a short length of time. There just didn’t appear to be enough time to attach the debugger, then immediately continue. Network connectivity gets lost, and the switch becomes no longer responsive.</p>

<p>Bummer…</p>

<p>My guess is that there’s some kind of watchdog mechanism that’s shutting down the system if the main system binary doesn’t seem responsive. No idea if that’s actually the case. In any case, it wouldn’t really help, so I didn’t bother looking any deeper.</p>

<h2 id="second-attempt-writing-a-program-to-dump-i2c-registers">Second attempt: writing a program to dump I2C registers</h2>

<p>For my second attempt, I took a more black-box approach. Perhaps I could dump out the register state of the controller chip, then compare the values between configuration changes in the Web UI.</p>

<h3 id="interacting-with-the-i2c-controller">Interacting with the I2C controller</h3>

<p>Sadly, the stock kernel doesn’t implement proper I2C drivers, so I couldn’t just run something like <code class="language-plaintext highlighter-rouge">i2cdump</code>. Some digging in the stock firmware revealed a proprietary kernel module called <code class="language-plaintext highlighter-rouge">rtcore.ko</code> was being used to arbitrate access to the switch hardware - including implementing the GPIO bit-bang’d I2C bus on which the PoE controller chip lives. The way that the system binary interacts with this kernel module is through opening a magic character device under <code class="language-plaintext highlighter-rouge">/dev/rtcore</code> and making special <code class="language-plaintext highlighter-rouge">ioctl</code> calls.</p>

<p>With the help of Ghidra and some header files found in the source code, I was able to construct a function from scratch that does something functionally identical to what the system binary does:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>struct ioctl_i2c_read {
        int32_t ret;
        uint32_t drv_type;
        uint32_t dev;
        uint32_t reg;
        uint32_t data;
};

int32_t drv_gpio_i2c_read(uint8_t drv_type, uint32_t dev, uint32_t reg, uint32_t *data) {
        int fd = open("/dev/rtcore", O_RDWR);
        if (fd &lt; 0)
                return -1;

        struct ioctl_i2c_read req = {
                .drv_type = drv_type,
                .dev = dev,
                .reg = reg,
        };
        ioctl(fd, 0xc0045251, &amp;req);
        close(fd);

        *data = req.data;
        return req.ret;
}
</code></pre></div></div>

<p>The parameter names are the same names used in the header files included with the source code release. It’s not immediately clear what <code class="language-plaintext highlighter-rouge">drv_type</code> does, but the system binary always seems to set this to zero. <code class="language-plaintext highlighter-rouge">dev</code> is the I2C address of the device. <code class="language-plaintext highlighter-rouge">reg</code> is the register number to be read.</p>

<p>(Incidentally, I found the choice of data types odd. I2C addresses are typically 7 bits, and register numbers and values are typically 8 bits, yet all the data types representing them are 32-bit integers).</p>

<p>The userspace code populates the structure containing the parameters for a I2C read request, and makes the magic ioctl call. The ioctl handler executes the request and populates the return code and data from the I2C transaction (or zero if it failed).</p>

<h3 id="dumping-the-hardware-register-state">Dumping the hardware register state</h3>

<p>The address of the PoE controller chip can be determined with the help of the datasheet and careful inspection of the circuit board. The top 3 bits of the address are fixed, and the bottom 4 bits are determined by whether certain pins are pulled high or low.</p>

<p>Now that both the method for interacting with the I2C bus and the address of the PoE controller was known, writing a short C program to exhaustively dump all the registers was relatively trivial.</p>

<p>Using that program, I dumped the hardware register state, and saved the output to a file. Then, I made a change in the Web UI changing a port’s power limits, and dumped the hardware register state again, saving the output to a file.</p>

<p>Interestingly, the diff revealed no differences in the current limit configurations. Regardless of the power figures configured in the Web UI, the hardware per-port current limits remained identical. The only differences appeared to be differences in status register values and the ADC readings of voltages and currents. If any per-port power limiting was being enforced, it didn’t appear to be done in hardware.</p>

<p>Clearly more investigation was warranted.</p>

<h2 id="third-attempt-strace">Third attempt: strace</h2>

<p>Since it’s now known that the I2C transactions are faciliated using <code class="language-plaintext highlighter-rouge">ioctl</code> syscalls, there wasn’t really a need to attach a full debugger onto the system binary process and risk locking the system up. We can use <code class="language-plaintext highlighter-rouge">strace</code> to show all the I2C-related ioctl calls and the contents of any data that is read or written.</p>

<p>Like with <code class="language-plaintext highlighter-rouge">gdbserver</code>, I had some trouble cross-compiling some of the more recent versions of <code class="language-plaintext highlighter-rouge">strace</code>, so I also needed to find an older version (more specifically, version 6.7 which was about 1.5 years old at time of writing).</p>

<h3 id="partial-success">Partial success</h3>

<p>I invoked strace and attached it to the process of interest with <code class="language-plaintext highlighter-rouge">./strace -f -e trace=ioctl -p 104</code>. Note that it’s important to filter to ioctl syscalls only, since I found tracing everything would occasionally pause the process long enough to lock up the system.</p>

<p>The good news was that this showed a bunch of lines that were of interest:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>[pid   612] ioctl(86, _IOC(_IOC_READ|_IOC_WRITE, 0x52, 0x51, 0x4), 0x30724e10) = 0
</code></pre></div></div>

<p>There were all sorts of ioctls that were related to I2C transactions - both reads and writes to the PoE controller.</p>

<p>The bad news was that <code class="language-plaintext highlighter-rouge">strace</code> does not understand the custom ioctl numbers, and thus doesn’t know how to decode the argument. It just prints a raw pointer value, which isn’t helpful at all since we’re interested in the data that the pointer <em>points to</em>. It would be nice if we could actually see exactly what data the syscall was returning with.</p>

<h3 id="patching-strace">Patching strace</h3>

<p>I ended up patching my version of strace to print out the struct field values for the ioctls of interest (instead of just a raw pointer value). I was pleasantly surprised to find how little code I had to hack to make this work:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>--- strace-6.7/src/ioctl.c	2023-02-26 08:00:00.000000000 +0000
+++ strace-6.7-modified/src/ioctl.c	2025-10-01 15:22:21.861449958 +0000
@@ -320,6 +320,43 @@
 	return rc;
 }
 
+struct rtcore_i2c_op {
+	int32_t ret;
+	uint32_t drv_type;
+	uint32_t dev;
+	uint32_t reg;
+	uint32_t data;
+};
+
+static int
+rtcore_ioctl(struct tcb *tcp, const unsigned int code, const kernel_ulong_t addr)
+{
+	if (entering(tcp)) {
+		return 0;
+	}
+
+	struct rtcore_i2c_op op;
+	switch (_IOC_NR(code)) {
+	case 0x51: // drv_gpio_i2c_read
+	case 0x52: // drv_gpio_i2c_write
+		if (!umove_or_printaddr(tcp, addr, &amp;op)) {
+			tprint_struct_begin();
+			PRINT_FIELD_D(op, ret);
+			tprint_struct_next();
+			PRINT_FIELD_X(op, drv_type);
+			tprint_struct_next();
+			PRINT_FIELD_X(op, dev);
+			tprint_struct_next();
+			PRINT_FIELD_X(op, reg);
+			tprint_struct_next();
+			PRINT_FIELD_X(op, data);
+			tprint_struct_end();
+			return RVAL_IOCTL_DECODED;
+		}
+	}
+	return RVAL_DECODED;
+}
+
 /**
  * Decode arg parameter of the ioctl call.
  *
@@ -385,8 +422,9 @@
 		return mtd_ioctl(tcp, code, arg);
 	case 'O':
 		return ubi_ioctl(tcp, code, arg);
-	case 'R':
-		return random_ioctl(tcp, code, arg);
+	case 'R': /* 0x52 */
+		//return random_ioctl(tcp, code, arg);
+		return rtcore_ioctl(tcp, code, arg);
 	case 'T':
 		return term_ioctl(tcp, code, arg);
 	case 'V':
</code></pre></div></div>

<p>Points of interest:</p>

<ul>
  <li>The ioctl type number was already being used by a different ioctl, so decoding is <em>technically</em> ambiguous.
    <ul>
      <li>Not really a problem in our particular case since I don’t believe the other ioctl ever gets used by the system binary.</li>
    </ul>
  </li>
  <li>We only decode the struct arg upon <em>exiting</em> the syscall.
    <ul>
      <li>The system binary doesn’t initialize the <code class="language-plaintext highlighter-rouge">ret</code> or <code class="language-plaintext highlighter-rouge">data</code> fields on reads, since it’s expecting the ioctl call to populate them.</li>
      <li>If we decode the struct arg prior to entering the syscall, those fields contain garbage, making the output more difficult to reason about.</li>
    </ul>
  </li>
  <li>It turns out that the ioctl to write to the I2C device uses an identical structure, so also supporting decodes of write ioctls was trivial.</li>
</ul>

<h3 id="success">Success</h3>

<p>With a patched <code class="language-plaintext highlighter-rouge">strace</code>, we get far more meaningful output:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>[pid   612] ioctl(87, _IOC(_IOC_READ|_IOC_WRITE, 0x52, 0x51, 0x4){ret=0, drv_type=0, dev=0x21, reg=0x2c, data=0}) = 0
</code></pre></div></div>

<p>Nice.</p>

<h2 id="the-not-so-exciting-conclusion">The (not so) exciting conclusion</h2>

<p>The <code class="language-plaintext highlighter-rouge">strace</code> output turned out to be consistent with our hypothesis that per-port power limits weren’t being enforced in hardware.</p>

<p>There was a handful of status registers that were being polled repeatedly, almost as quickly as if it were done in a tight loop. Once a PoE device was connected, per-port voltages and currents values also started being polled repeatedly.</p>

<p>From this, I concluded that per-port power limits were enforced entirely in software (or not enforced at all). My guess is that it’s repeatedly sampling the instantaneous voltage and current to calculate the instantaneous power figure, and manually shutting down the port if it goes over the configured limits.</p>

<p>In any case, this is enough information for me to write a safe Linux driver, so I will declare success for now.</p>]]></content><author><name></name></author><summary type="html"><![CDATA[In my previous post, I wrote about how I obtained root on the stock firmware of my switch to try to figure out how the stock firmware was implementing per-port power limits. The next step was to actually perform the introspection into what the stock firmware was doing.]]></summary></entry><entry><title type="html">Reverse engineering PoE on the TL-SG2008P V3 firmware - Part 1</title><link href="https://blog.tangrs.id.au/2025/09/30/reverse-engineering-poe-tl-sg2008p-v3-part-1/" rel="alternate" type="text/html" title="Reverse engineering PoE on the TL-SG2008P V3 firmware - Part 1" /><published>2025-09-30T00:00:00+00:00</published><updated>2025-09-30T00:00:00+00:00</updated><id>https://blog.tangrs.id.au/2025/09/30/reverse-engineering-poe-tl-sg2008p-v3-part-1</id><content type="html" xml:base="https://blog.tangrs.id.au/2025/09/30/reverse-engineering-poe-tl-sg2008p-v3-part-1/"><![CDATA[<h2 id="background">Background</h2>

<p>I recently bought a cheap TP-Link switch in hopes that it would be able to run OpenWRT. Unfortunately, it seems like I bought the V3 variant of the board, whereas the <a href="https://openwrt.org/toh/hwdata/tp-link/tp-link_tl-sg2008p">existing OpenWRT port</a> only supports the V1 variant.</p>

<p>However, from poking around the firmware and looking at the board, the only difference appeared to be the PoE controller chip. The V1 has the TPS23861 chip, whereas the V3 has an MP3924. A reasonably fully-featured OpenWRT port to the V3 variant doesn’t appear terribly difficult if we can somehow support the different PoE controller. Unfortunately, at the time of writing, the MP3924 has no Linux driver support.</p>

<p>In order to write a driver that would operate safely, I wanted to first find out how the stock firmware configures the PoE controller (more specifically, how it configures the power limits).</p>

<p>In particular, the stock Web UI allows setting custom power limits on individual ports in watts, but the datasheet for the MP3924 seems to suggest that the over-current protection limits must be configured in milliamps. I’m guessing that the firmware assumes a input voltage, and uses that to work backwards from a power figure to a current figure. However, I wanted to make sure, since this could end up being a safety-related issue if the driver does not correctly configure the over-current protections for this particular hardware.</p>

<h2 id="the-plan">The plan</h2>

<ol>
  <li>Get a root shell into the stock firmware to faciliate experimentation.</li>
  <li>Make a change in the Web UI regarding power limits.</li>
  <li>Somehow read back the hardware registers to see what changed.</li>
  <li>Go to step 2.</li>
</ol>

<p>In this particular post, I will be focusing on step 1.</p>

<h2 id="hardware-modifications">Hardware modifications</h2>

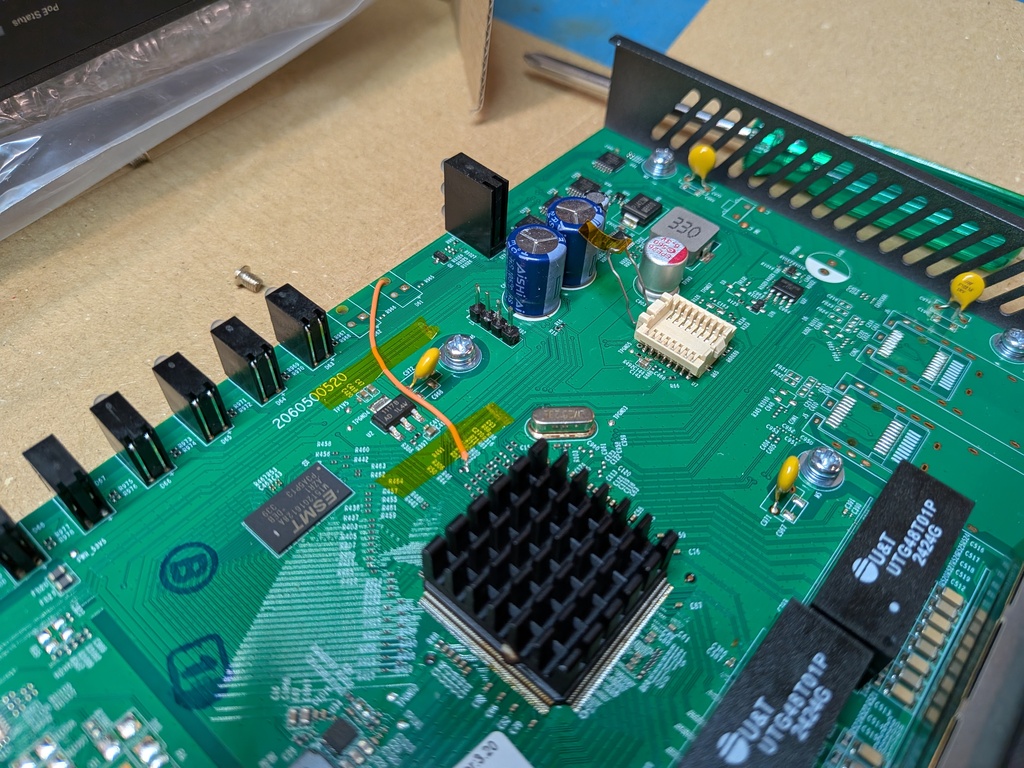
<p><img src="/assets/2025/09/30/sg2008p-hardware-mods.jpg" alt="" /></p>

<p>I don’t know of any software vulnerabilities in the current firmware version that would allow us to get root via purely software means so my plan was to obtain root by modifying the firmware image using a hardware flasher. To faciliate this, I desoldered the flash chip, and soldered a <a href="https://www.adafruit.com/product/4727">socket</a> that would allow me to easily move the flash chip to/from a hardware flasher.</p>

<p>Furthermore, when working on embedded platforms, it’s always useful to have a serial port for debugging, so I also soldered on pin headers. Unfortunately, the serial port header also <a href="https://git.openwrt.org/?p=openwrt/openwrt.git;a=commit;h=6d5873a162e9e03c93012a26b0004d46e6764a8e">requires adding solder bridges (or 0 ohm resistors) to some pads</a>, and I wasn’t able to get a solder bridge to form reliably. I ended up soldering a bodge wire instead.</p>

<h2 id="the-stock-firmware-boot-process">The stock firmware boot process</h2>

<p>The onboard flash has roughly the following partitions:</p>

<ul>
  <li>Bootloader</li>
  <li>Kernel
    <ul>
      <li>The kernel has a built-in initramfs, which appears to be a standard buildroot root filesystem.</li>
      <li>Houses TP-Link’s custom init script.</li>
    </ul>
  </li>
  <li>Two squashfs images
    <ul>
      <li>These images contain all of TP-Link’s proprietary binaries.</li>
      <li>There are two since the switch supports “dual booting”, presumably to allow recovery from a bad firmware update.</li>
      <li>I didn’t look too closely, but there’s likely some boot variable that the start-up script reads in order to pick the right image.</li>
    </ul>
  </li>
  <li>A JFFS2 filesystem
    <ul>
      <li>This looks like where user settings are persisted.</li>
    </ul>
  </li>
</ul>

<p>At a high-level, the stock firmware boot process does the following:</p>

<ol>
  <li>Mount one of the two squashfs images, depending on which is the “active” one.</li>
  <li>Mount the JFFS2 filesystem, containing the persisted user settings.</li>
  <li>Run the proprietary TP-Link startup binary located in the squashfs image.</li>
</ol>

<p>The full startup script can be found in TP-Link’s GPL source code release for the firmware.</p>

<h2 id="hijacking-the-boot-process-to-run-an-ssh-daemon">Hijacking the boot process to run an SSH daemon</h2>

<p>To me, the most straightforward approach to getting a root shell was to modify the squashfs image to include a statically compiled SSH server that we can use to log in as root. <a href="https://matt.ucc.asn.au/dropbear/dropbear.html">Dropbear</a> is a commonly used and favoured SSH server for embedded devices due to its size and simplicity, so that’s what I used.</p>

<p>To hook into the startup process, I replaced the normal TP-Link startup binary with a wrapper script that starts dropbear, then execs the real startup binary:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>#!/bin/sh

mkdir -p /tplink/usrapp/dropbear
ln -sf /tplink/usrapp/dropbear /etc/dropbear
ln -sf /tplink/image/dropbear/dropbearmulti /sbin/dropbear
ln -sf /tplink/image/dropbear/dropbearmulti /bin/scp
ln -sf /tplink/image/dropbear/dropbearmulti /bin/dropbearkey
ln -sf /tplink/image/dropbear/dropbearmulti /bin/dropbearconvert
ln -sf /tplink/image/dropbear/dropbearmulti /bin/dbclient
cp /tplink/image/dropbear/shadow /etc/shadow

/sbin/dropbear -E -p 1234 -R

exec /tplink/image/usrImage/app/sbin/core.real
</code></pre></div></div>

<p>In high-level terms, the script does the following:</p>

<ol>
  <li>Creates a folder on the JFFS2 persistent storage for storing dropbear config (if it doesn’t already exist).
    <ul>
      <li>We use persistent storage here to avoid having to generate a new host key on every boot.</li>
    </ul>
  </li>
  <li>Creates symlinks under <code class="language-plaintext highlighter-rouge">/sbin</code> and <code class="language-plaintext highlighter-rouge">/bin</code> to the <code class="language-plaintext highlighter-rouge">dropbearmulti</code> binary.</li>
  <li>Overwrites <code class="language-plaintext highlighter-rouge">/etc/shadow</code> with a copy where root has a known password.</li>
  <li>Runs the <code class="language-plaintext highlighter-rouge">dropbear</code> daemon on an unused port.</li>
  <li>Execs the real startup binary.</li>
</ol>

<p>(Note that the squashfs image is mounted under <code class="language-plaintext highlighter-rouge">/tplink/image</code>, and the persistent JFFS2 filesystem is mounted under <code class="language-plaintext highlighter-rouge">/tplink/usrapp</code>).</p>

<h3 id="building-dropbear">Building dropbear</h3>

<p>Cross-compiling dropbear was relatively straightforward using the precompiled toolchain found in TP-Link’s GPL source code release. Note that you may need to install 32-bit libraries if running on a x86_64 system. On Debian, this is just <code class="language-plaintext highlighter-rouge">sudo apt install ia32-libs</code>.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>export PATH="${PATH?}:/path/to/gpl/source/omada_switch/20161108_WebUI_upgrade/tplink/buildroot-realtek/ext-tools/msdk-4.3.6-mips-EB-2.6.32-0.9.33/host/usr/bin/"
./configure --host=mips-linux --enable-static --disable-zlib
make PROGRAMS="dropbear dbclient dropbearkey dropbearconvert scp" MULTI=1 -j8
</code></pre></div></div>

<h3 id="generating-a-new-etcshadow">Generating a new /etc/shadow</h3>

<p>For this, I just copied the existing <code class="language-plaintext highlighter-rouge">/etc/shadow</code> and generated a password hash for <code class="language-plaintext highlighter-rouge">root</code>. This password hash can be generated using <code class="language-plaintext highlighter-rouge">openssl passwd -1 &lt;your password&gt;</code>.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>root:$1$tie/0Ymw$9ucfZx.CpHktEDumfb13D1:10933:0:99999:7:::
bin:*:10933:0:99999:7:::
daemon:*:10933:0:99999:7:::
adm:*:10933:0:99999:7:::
lp:*:10933:0:99999:7:::
sync:*:10933:0:99999:7:::
shutdown:*:10933:0:99999:7:::
halt:*:10933:0:99999:7:::
uucp:*:10933:0:99999:7:::
operator:*:10933:0:99999:7:::
ftp:*:10933:0:99999:7:::
nobody:*:10933:0:99999:7:::
default::10933:0:99999:7:::
</code></pre></div></div>

<h3 id="notes-on-patching-the-squashfs-image">Notes on patching the squashfs image</h3>

<p>I performed all image manipulation (unpacking, modifying, re-packing) all in a single <code class="language-plaintext highlighter-rouge">fakeroot</code> session in order to preserve ownership and permissions. Real <code class="language-plaintext highlighter-rouge">root</code> is <em>not</em> required.</p>

<p>The image can be unpacked with <code class="language-plaintext highlighter-rouge">unsquashfs /path/to/image.bin</code>. This extracts the image to a folder called <code class="language-plaintext highlighter-rouge">squashfs-root</code>. Check that the exit code is zero to ensure that all permissions and ownership bits were preserved in the extraction process (it will have <a href="https://manpages.debian.org/testing/squashfs-tools/unsquashfs.1.en.html#EXIT_STATUS">an exit code of 2 if it failed to do so</a>).</p>

<p>Once the filesystem tree is patched, the image can be re-packed with <code class="language-plaintext highlighter-rouge">mksquashfs squashfs-root/ squashfs.bin -comp lzma</code>.</p>

<p>Once the squashfs image has been re-packed, it can be spliced into a flash dump for writing back into the onboard storage. I didn’t look too hard into how the startup script chooses which image to mount, so I just replaced both:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>dd if=squashfs.bin of=flash-modded.bin seek=1792 bs=4096 conv=notrunc
dd if=squashfs.bin of=flash-modded.bin seek=4352 bs=4096 conv=notrunc
</code></pre></div></div>

<h2 id="getting-root">Getting root</h2>

<p>Once the switch finished booting, I was able to get root access through SSH 🎉:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code> % ssh root@192.168.0.1 -p 1234
The authenticity of host '[192.168.0.1]:1234 ([192.168.0.1]:1234)' can't be established.
ED25519 key fingerprint is SHA256:kBKqsC8m0s0OPQlkNiNtLJ4fCAQSchJeTRqcb0smwu8.
This key is not known by any other names.
Are you sure you want to continue connecting (yes/no/[fingerprint])? yes
Warning: Permanently added '[192.168.0.1]:1234' (ED25519) to the list of known hosts.
root@192.168.0.1's password: 


        Welcome to Layer 2 Managed Switch


  Press &lt;Enter&gt; to continue...
~ # busybox id
uid=0(root) gid=0(root) groups=0(root),10(wheel)
~ # uname -a
Linux streamOs 2.6.32.58 #2 Fri Aug 18 20:12:27 CST 2023 mips GNU/Linux
/ # exit
Connection to 192.168.0.1 closed.
</code></pre></div></div>

<p>I was also able to <code class="language-plaintext highlighter-rouge">scp</code> a test file 🎉:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code> % scp -O -P 1234 test root@192.168.0.1:/ 
root@192.168.0.1's password: 
test                                          100%    0     0.0KB/s   00:00    
</code></pre></div></div>

<p>Having root access and being able to scp arbitrary files to the switch should make it much easier to poke around on the stock firmware. I plan to document the actual reverse engineering of the PoE controller in <a href="/2025/10/05/reverse-engineering-poe-tl-sg2008p-v3-part-2/">the next post</a>.</p>]]></content><author><name></name></author><summary type="html"><![CDATA[Background]]></summary></entry><entry><title type="html">Decrypting TP-Link Smart Switch firmware</title><link href="https://blog.tangrs.id.au/2025/09/22/decrypting-tplink-smart-switch-firmware/" rel="alternate" type="text/html" title="Decrypting TP-Link Smart Switch firmware" /><published>2025-09-22T00:00:00+00:00</published><updated>2025-09-22T00:00:00+00:00</updated><id>https://blog.tangrs.id.au/2025/09/22/decrypting-tplink-smart-switch-firmware</id><content type="html" xml:base="https://blog.tangrs.id.au/2025/09/22/decrypting-tplink-smart-switch-firmware/"><![CDATA[<p>I recently acquired a TL-SG2008P and was hoping to do some research on the stock firmware for various reasons (mostly curiosity). Unfortunately, the firmware images made available by TP-Link on their website seemed to be encrypted, so it wasn’t a trivial matter of running <code class="language-plaintext highlighter-rouge">binwalk</code> on the image.</p>

<p>The simpler, but somewhat tedious solution would be to desolder the flash chip from the board and read the unencrypted firmware image from there. However, I didn’t have access to the tooling to do so at the time. Thus, I looked to see if there were other ways to get the unencrypted firmware image.</p>

<p>I figured that whatever encryption mechanism was being used, the key material was likely embedded inside the firmware image itself since the device would need to somehow decrypt the image before flashing it. This presents an issue, since we would need access to the unencrypted firmware image in order to find the decryption key.</p>

<p>The good news is that TP-Link used GPL’d code, and thus has published the source code for their firmware. It looks to be using an extremely old version of Linux (2.6.32!!), and a buildroot root filesystem (overlayed with a custom init script, and TP-Link’s proprietary system binaries). Some of the READMEs suggests that the source code is sufficient to build a full firmware image (albeit unencrypted).</p>

<p>I popped a few of the TP-Link binaries into Ghidra and was able to quickly find that the firmware image was being encrypted using DES-CBC with a hard-coded key + IV.</p>

<p>Incidentally, I found the choice of algorithm interesting. From the fact that an old and known-insecure encryption algorithm was being used with a hard-coded key and IV, I can only conclude that this is merely an obfuscation mechanism intended to prevent casual reverse-engineering of firmware images rather than a serious attempt to protect the contents of the image. Even if the source code wasn’t available, the key and IV can always be dumped from a physical device.</p>

<p>Nonetheless, I will follow the lead of other <a href="https://github.com/watchfulip/tp-link-decrypt">similar projects</a>, and not directly publish the keying material. Instead, I have included a shell one-liner below to extract the key material from the source code <a href="https://static.tp-link.com/resources/gpl/rtk-maple_gpl.tar.gz">available on TP-Link’s website</a>.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>tar -xzf rtk-maple_gpl.tar.gz -O omada_switch/20161108_WebUI_upgrade/tplink/buildroot-realtek/board/realtek/common/skeleton/tplink/lib/libservice.so.0 |\
    tee /dev/null |\
    od -j 907888 -N 16 -t x1 -A n |\
    tr -d '[:space:]' |\
    sed -r 's/^([a-f0-9]{16})([a-f0-9]{16})$/Key: \1  IV: \2\n/'
</code></pre></div></div>

<p>Note: the above is only tested with a <code class="language-plaintext highlighter-rouge">rtk-maple_gpl.tar.gz</code> having the following SHA256 hash: <code class="language-plaintext highlighter-rouge">6941bc1e4b979ecd7bd5c1a4d17f933f525a87e08004cd3efdec218ba581d34e</code></p>

<p>The firmware can be decrypted using the following OpenSSL command:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>openssl des-cbc \
    -provider legacy \
    -d -nopad \
    -K "${KEY?}" -iv "${IV?}" \
    -in encrypted.bin \
    -out decrypted.bin
</code></pre></div></div>

<p>It’s also worth noting that knowing the encryption key <em>does not</em> appear to be sufficient for crafting a valid firmware image. I did not confirm this, but the code does appear to perform an RSA signature check before proceeding with flashing a firmware image. It’s also not-yet-clear <em>where</em> this signature is located in the firmware image (likely at the end), but the signature does appear to be 128 bytes in size, suggesting a 1024-bit RSA signing key.</p>

<p>I hope this is useful for anyone hoping to conduct research on these firmware images.</p>]]></content><author><name></name></author><summary type="html"><![CDATA[I recently acquired a TL-SG2008P and was hoping to do some research on the stock firmware for various reasons (mostly curiosity). Unfortunately, the firmware images made available by TP-Link on their website seemed to be encrypted, so it wasn’t a trivial matter of running binwalk on the image.]]></summary></entry><entry><title type="html">Basic fan control for the Asustor Lockerstor Gen2 in TrueNAS</title><link href="https://blog.tangrs.id.au/2025/08/30/basic-fan-control-asustor-lockerstor-gen2/" rel="alternate" type="text/html" title="Basic fan control for the Asustor Lockerstor Gen2 in TrueNAS" /><published>2025-08-30T00:00:00+00:00</published><updated>2025-08-30T00:00:00+00:00</updated><id>https://blog.tangrs.id.au/2025/08/30/basic-fan-control-asustor-lockerstor-gen2</id><content type="html" xml:base="https://blog.tangrs.id.au/2025/08/30/basic-fan-control-asustor-lockerstor-gen2/"><![CDATA[<p>With the warmer months coming up, I started to worry about the low fixed speed of the built-in fan of my Asustor Lockerstor Gen2 NAS running TrueNAS. When using the default Asustor software, there’s a userspace daemon that presumably monitors temperatures of the CPU and drives and adjusts the fan speed accordingly. However, there is no such fan control mechanism by default in TrueNAS.</p>

<p>On start-up, the PWM signal to control the fan speed is fixed at 20%, which seems adequate at idle. However, when the drives are under load, the reported temperatures seems to average around the 40C to 45C mark. Toshiba seems to <a href="https://web.archive.org/web/20250607045444/https://www.toshiba-storage.com/wp-content/uploads/2022/07/Toshiba_OpenE_Blogpost_July2022_final.pdf">recommend keeping drives below 40C</a>, so it seems prudent to bump the fan speed a little, even though the drives themselves are probably rated up to 60C.</p>

<p>Unfortunately, as I mentioned in my previous post about controlling the <a href="/2025/08/14/basic-truenas-support-for-display-led-asustor-lockerstor-gen2/">status LEDs and LCD display in TrueNAS</a>, the IT8625E Super I/O chip (which control the fans) is not currently supported in the mainline Linux driver.</p>

<p>There are out-of-tree drivers that do support the chip, such as the <a href="https://github.com/mafredri/asustor-platform-driver/tree/main">asustor-platform-driver</a>, which seem to work well for people. However, like in my previous post, I wasn’t comfortable running 3rd-party drivers on my NAS for a variety of reasons.</p>

<p>Having looked at the datasheet for the <a href="https://web.archive.org/web/20250426125618/https://shop.asustor.com/index.php?route=product/product&amp;product_id=82">built-in fan</a>, it looks like it’s capable of pulling a decent amount of air. Even at the current fixed 20% fan speed, it doesn’t seem to be performing <em>terribly</em>. I figured just a minor bump might still keep the machine quiet without dynamic fan control, but still shave off a few degrees on the drives.</p>

<p>Luckily, there’s only just one register that needs to be changed, and it can also be done easily with a single <code class="language-plaintext highlighter-rouge">isaset</code> call. As usual, use the following at your own risk:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>isaset -y 0xa35 0xa36 0x63 &lt;PWM duty cycle (0x00 to 0xff)&gt;
</code></pre></div></div>

<p>By running the above as a <a href="https://www.truenas.com/docs/scale/scaletutorials/systemsettings/advanced/manageinitshutdownscale/">pre-init command</a>, it can be used to set the fan percentage on startup.</p>

<p>For convenience, I’ve precalculated PWM duty cycle values for common fan percentages:</p>

<table>
  <tbody>
    <tr>
      <td>10%</td>
      <td><code class="language-plaintext highlighter-rouge">0x19</code></td>
    </tr>
    <tr>
      <td>20% (default)</td>
      <td><code class="language-plaintext highlighter-rouge">0x33</code></td>
    </tr>
    <tr>
      <td>30%</td>
      <td><code class="language-plaintext highlighter-rouge">0x4c</code></td>
    </tr>
    <tr>
      <td>40%</td>
      <td><code class="language-plaintext highlighter-rouge">0x66</code></td>
    </tr>
    <tr>
      <td>50%</td>
      <td><code class="language-plaintext highlighter-rouge">0x7f</code></td>
    </tr>
    <tr>
      <td>60%</td>
      <td><code class="language-plaintext highlighter-rouge">0x99</code></td>
    </tr>
    <tr>
      <td>70%</td>
      <td><code class="language-plaintext highlighter-rouge">0xb2</code></td>
    </tr>
    <tr>
      <td>80%</td>
      <td><code class="language-plaintext highlighter-rouge">0xcc</code></td>
    </tr>
    <tr>
      <td>90%</td>
      <td><code class="language-plaintext highlighter-rouge">0xe5</code></td>
    </tr>
    <tr>
      <td>100%</td>
      <td><code class="language-plaintext highlighter-rouge">0xff</code></td>
    </tr>
  </tbody>
</table>

<p>For me, I’ve found that 30% was a good balance between lower temperatures while still remaining relatively silent.</p>

<h2 id="closing-thoughts">Closing thoughts</h2>

<p>As I mentioned in my previous post, ideally the Super I/O chip would be supported in the upstream Linux drivers so we wouldn’t need to directly write to hardware registers from user-space. Until then, I’ll be using the above.</p>]]></content><author><name></name></author><summary type="html"><![CDATA[With the warmer months coming up, I started to worry about the low fixed speed of the built-in fan of my Asustor Lockerstor Gen2 NAS running TrueNAS. When using the default Asustor software, there’s a userspace daemon that presumably monitors temperatures of the CPU and drives and adjusts the fan speed accordingly. However, there is no such fan control mechanism by default in TrueNAS.]]></summary></entry></feed>